About Me关于我
I am a Ph.D. student at Westlake University (Fall 2025), advised by Prof. Tailin Wu. I am deeply interested in the physics of intelligence. I do research to reduce my perplexity about the world we live in.
I study the interplay between representation learning and generative modeling, drawing on statistical physics and information theory. Some questions that guide my research are:
- How does the encoding distribution \(q(z_0\mid x)\) shape the learnability of generative models? RAE · REPA-E
- How does the forward process \(p_F(z_{0:T})\) shape the learnability of generative models? AO-GPT · Discussion on Zhihu (Chinese)
- How can representation-aware objectives enable few-step or one-step generation? Perceptual Flow Matching · Drifting Models
These questions guide my current focus on end-to-end (single-step) latent generative models: jointly learning representations and generators to achieve both efficient learning and few-step generation.
I am actively seeking internships with leading academic and industry research groups. Please get in touch if our interests overlap.
Previously, I studied astronomy at Nanjing University and the Australian National University, working with Prof. Yuan-Sen Ting.
我于 2025 年秋季进入西湖大学攻读博士学位,导师是吴泰霖老师。我对智能的物理学有浓厚兴趣。我做研究,是为了减少自己对我们所生活的世界的困惑。
我主要关注表示学习与生成模型之间的相互作用,并借助统计物理和信息论研究其中的规律。具体而言,我关心:
- 编码分布 \(q(z_0\mid x)\) 如何影响生成模型的可学习性?RAE · REPA-E
- 前向过程 \(p_F(z_{0:T})\) 如何影响生成模型的可学习性?AO-GPT · 知乎讨论
- 如何利用表示空间中的训练目标,实现少步或单步生成?Perceptual Flow Matching · Drifting Models
这些问题共同指向我目前的研究重点:端到端(单步)隐空间生成模型。通过联合学习表示与生成器,使模型兼具高效学习与少步生成能力。
我正在积极寻找顶尖学术团队与工业界研究机构的实习机会。如果研究兴趣契合,欢迎联系我。
此前,我在南京大学和澳大利亚国立大学学习天文,并与Yuan-Sen Ting 教授合作。
Research Highlight研究工作
Feature Information Dynamics in Diffusion
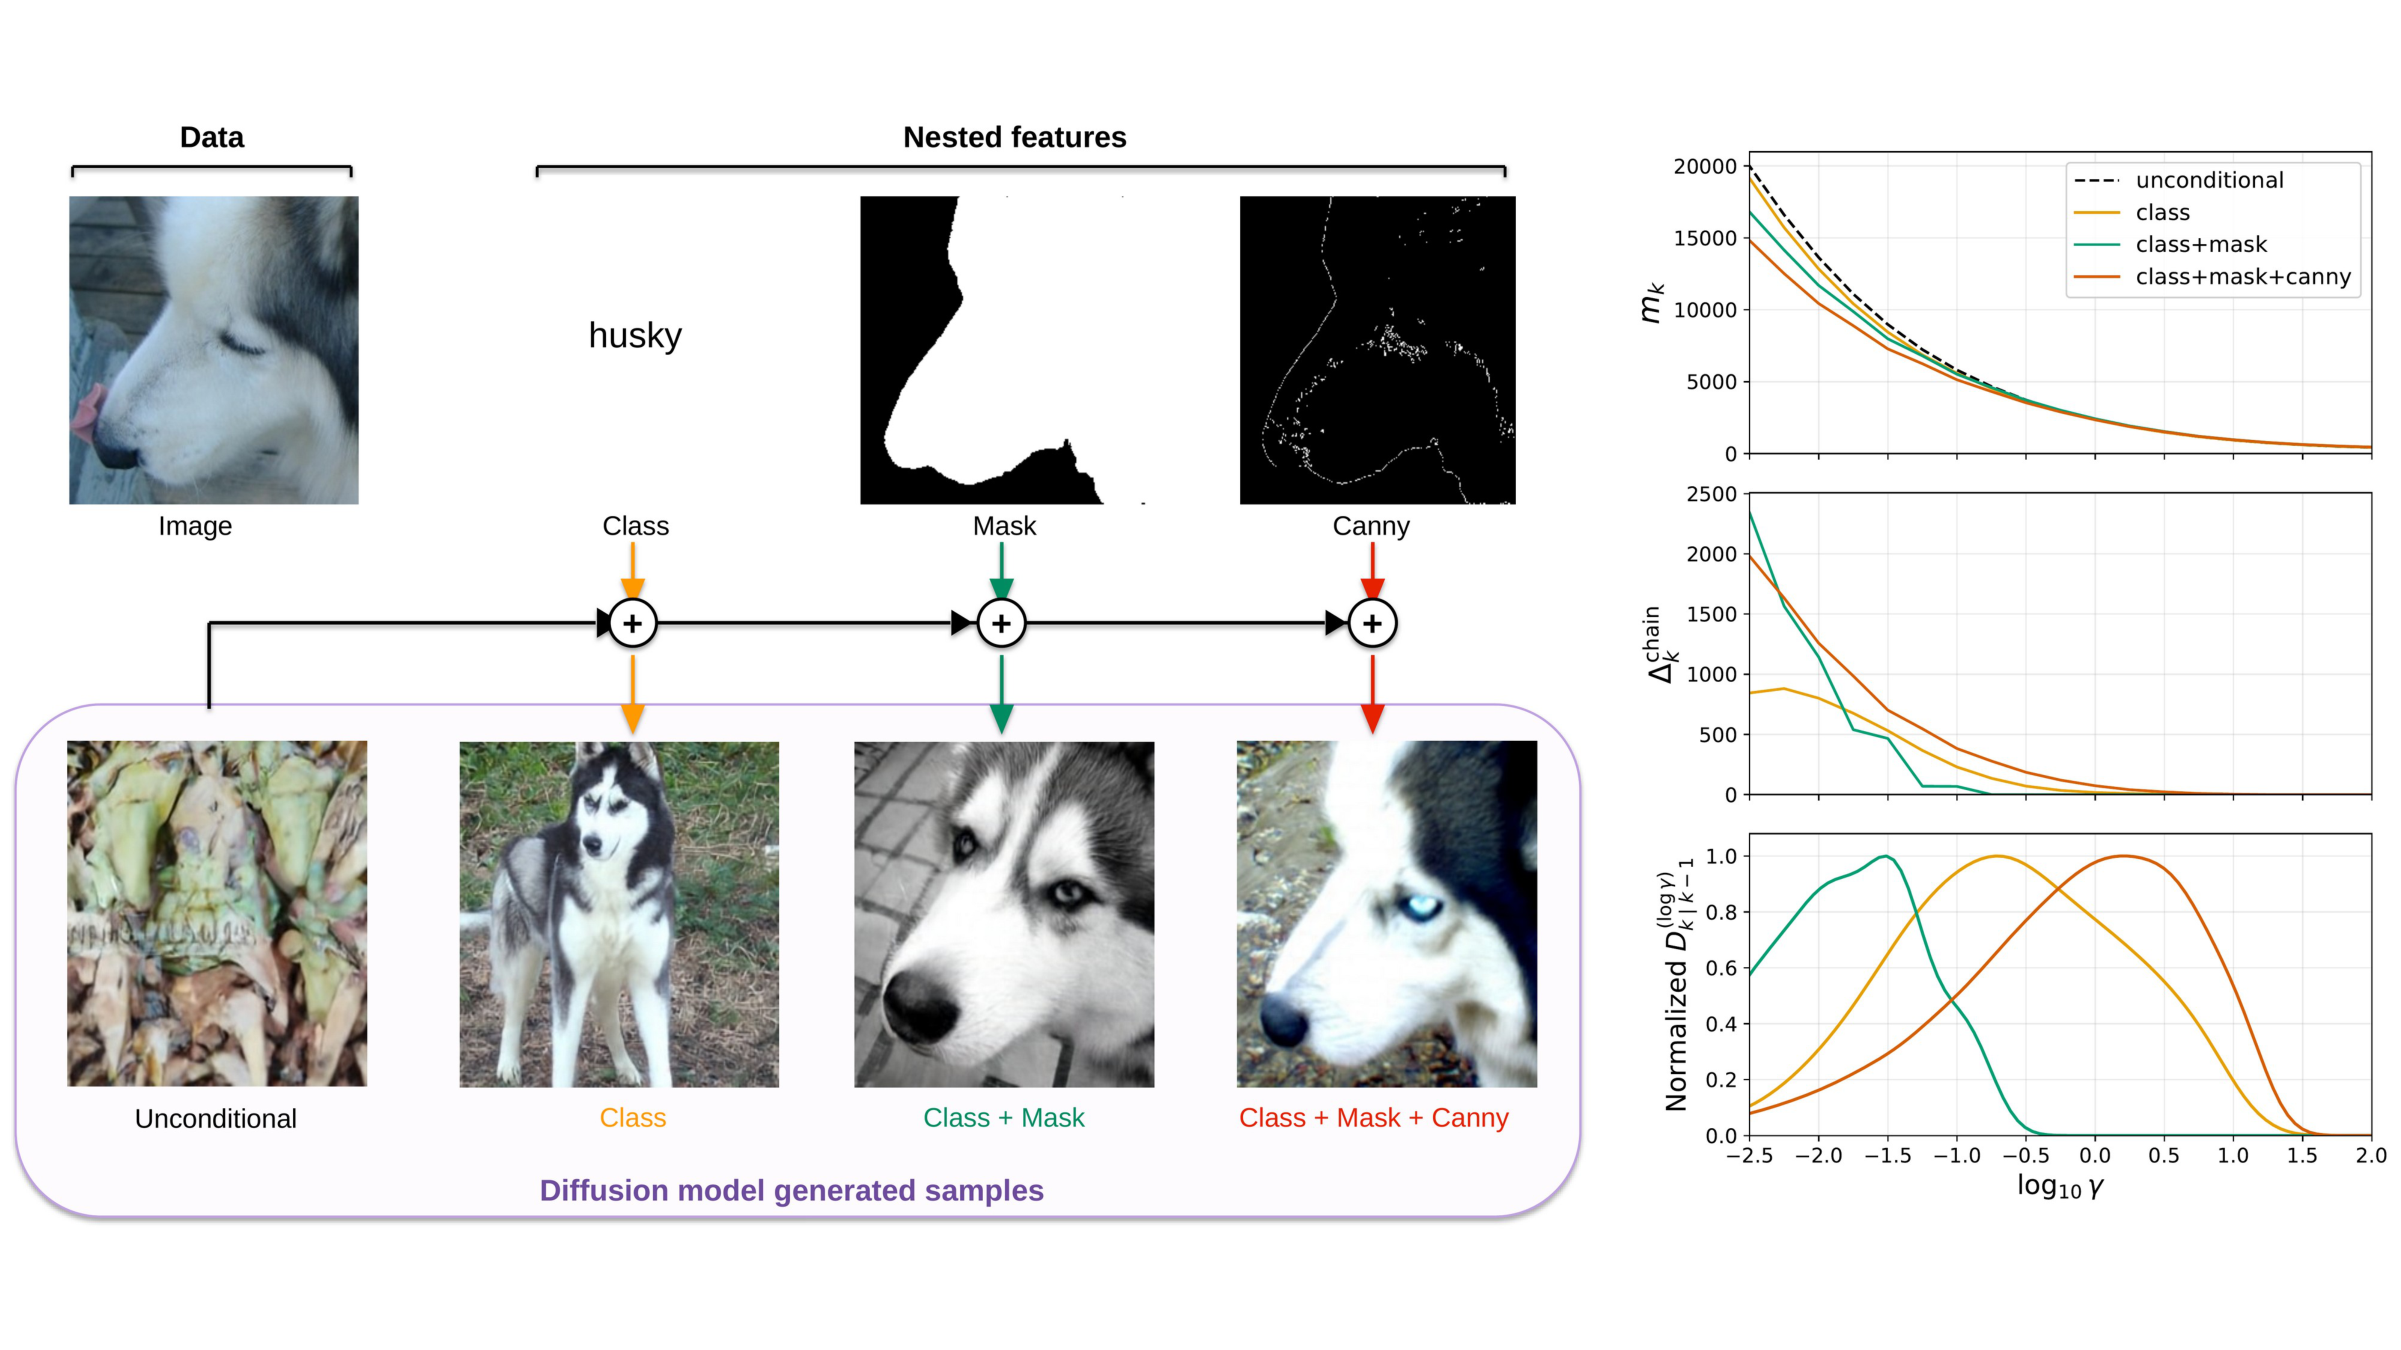
Using the I-MMSE relation, we define feature information density during diffusion for any feature in any representation space, quantifying the order in which different features emerge.
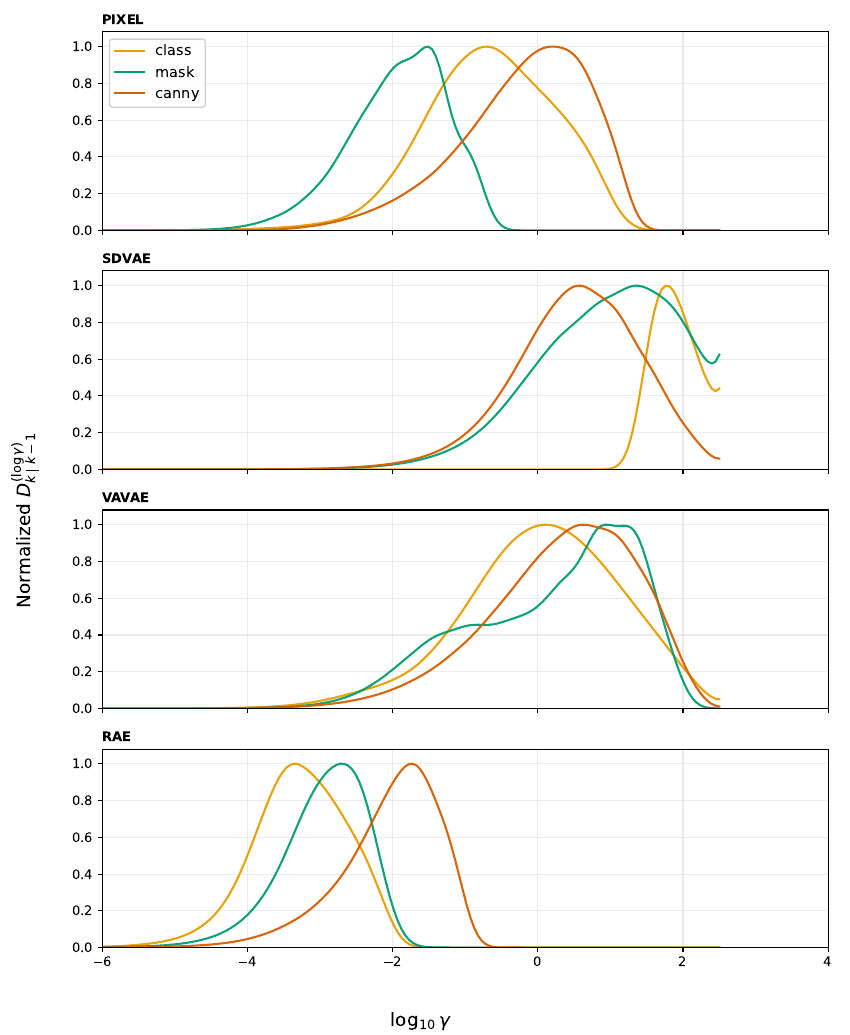
Across the four representation spaces we study, only RAE exhibits the class → mask → Canny order, and diffusion models converge fastest in this space. We hypothesize that these ordered feature dynamics help explain its faster convergence.
扩散模型中的特征信息动力学
利用 I-MMSE 关系,我们定义了任意表示空间上、任意特征在扩散中的特征信息密度,以量化不同特征在扩散过程中的出现顺序。
在我们研究的四种表示空间中,只有 RAE 呈现类别 → mask → Canny 的顺序,且其上的扩散模型收敛最快。我们猜测,这种有序的特征动力学可能解释其更快的训练收敛。
Collapse details 收起详情
Diffusion models generate data through a continuum of denoising problems, and are widely observed to reveal coarse structure before fine detail. Yet, this intuition is mostly empirical and qualitative—and, crucially, it need not hold after data are mapped into a representation space.
Feature information density
Let \(X\in\mathbb{R}^d\) be clean data (e.g., an image or latent), \(Y\) a feature of \(X\) (e.g., class, mask, or Canny), and \(X_\gamma=\sqrt{\gamma}X+N\) the Gaussian-corrupted data at signal-to-noise ratio \(\gamma\), where \(N\sim\mathcal{N}(0,I)\) is independent noise. We define the feature information density as
Intuitively, \(D_Y(\gamma)\) distributes the total information about \(Y\) along the SNR axis: it measures how much additional feature information becomes accessible from an infinitesimal increase in SNR. A peak therefore identifies the noise level at which that feature is revealed most rapidly during denoising.
Let \(m_\varnothing(\gamma)\) and \(m_Y(\gamma)\) denote the optimal unconditional and feature-conditional denoising losses (MMSE). Conditioning cannot increase this loss. I-MMSE connects feature information density to their difference:
Its trajectory across noise levels describes how that feature's information is distributed over the generation process. Empirically, we find that class, mask, and Canny information exhibit markedly different dynamics across pixel, SDVAE, VAVAE, and RAE spaces. Only RAE exhibits the class → mask → Canny order. We hypothesize that these ordered feature dynamics may explain why diffusion models converge fastest in the RAE space.
扩散模型通过一系列连续的去噪问题生成数据,人们普遍观察到它会先呈现粗粒度结构,再补充细节。然而,这一直主要是一种经验性的定性直觉;更关键的是,当数据被映射到表示空间后,这一 coarse-to-fine 直觉未必仍然成立。
特征信息密度
设 \(X\in\mathbb{R}^d\) 是干净数据(例如图像或 latent),\(Y\) 是 \(X\) 的某个特征(例如类别、mask 或 Canny),\(X_\gamma=\sqrt{\gamma}X+N\) 是信噪比 \(\gamma\) 下经过高斯扰动的数据,其中 \(N\sim\mathcal{N}(0,I)\) 是独立噪声。我们将特征信息密度定义为
直观上,\(D_Y(\gamma)\) 将关于 \(Y\) 的总信息量分布到信噪比轴上:它衡量信噪比增加无穷小量时,我们能从数据中多获得多少关于该特征的信息。因此,曲线的峰值对应这一特征在去噪过程中显现得最快的噪声水平。
\(m_\varnothing(\gamma)\) 和 \(m_Y(\gamma)\) 分别表示无条件与特征条件下的最优去噪损失(MMSE)。增加条件不会增大这一损失。I-MMSE 将特征信息密度与两者之差联系起来:
它随噪声水平变化的轨迹刻画了该特征信息在生成过程中的分布。经验上,我们发现类别、mask 和 Canny 信息在像素、SDVAE、VAVAE 与 RAE 空间中呈现显著不同的动力学。其中,只有 RAE 上的特征信息动力学服从类别 → mask → Canny 的顺序。我们猜测,这种有序的特征动力学可能正是扩散模型在 RAE 空间中收敛最快的原因。
Selected Publications代表论文
NeurIPS 2026
Feature Information Dynamics in Diffusion
A quantitative framework for locating hierarchical features along diffusion trajectories and relating their temporal organization to representation-dependent convergence.
定量定位层次特征在扩散轨迹中的生成时刻,并研究这种时间组织方式与不同表示空间收敛速度之间的关系。
ICLR 2026
VFScale: Intrinsic Reasoning through Verifier-Free Test-time Scalable Diffusion Model
* Equal contribution* 共同第一作者
VFScale trains a diffusion model's own energy to serve as a verifier and combines it with hybrid Monte Carlo Tree Search, enabling verifier-free test-time scaling on Maze and Sudoku.
VFScale 将扩散模型自身的能量训练为验证器,并结合混合蒙特卡洛树搜索,在迷宫与数独任务上实现无需外部验证器的测试时扩展。
Hobbies爱好
Contact联系我
Interesting questions, disagreements, and half-formed ideas are always welcome. If our research interests overlap, I would be happy to talk.
Email: panjiashu@westlake.edu.cn
有趣的问题、不同的意见和尚未成形的想法都很受欢迎。如果我们的研究兴趣有所交集,欢迎随时交流。
Last updated: 最后编辑: © 2026 Jia-Shu Pan · Built with Jekyll and al-folio · Website design inspired by Huanran Chen · Milky Way photographed by the author in the Tengger Desert on the night of August 12, 2026. © 2026 潘嘉书 · 使用 Jekyll 与 al-folio 构建 · 网站设计参考了陈焕然的个人主页 · 星空照片由本人于 2026 年 8 月 12 日晚摄于腾格里沙漠。